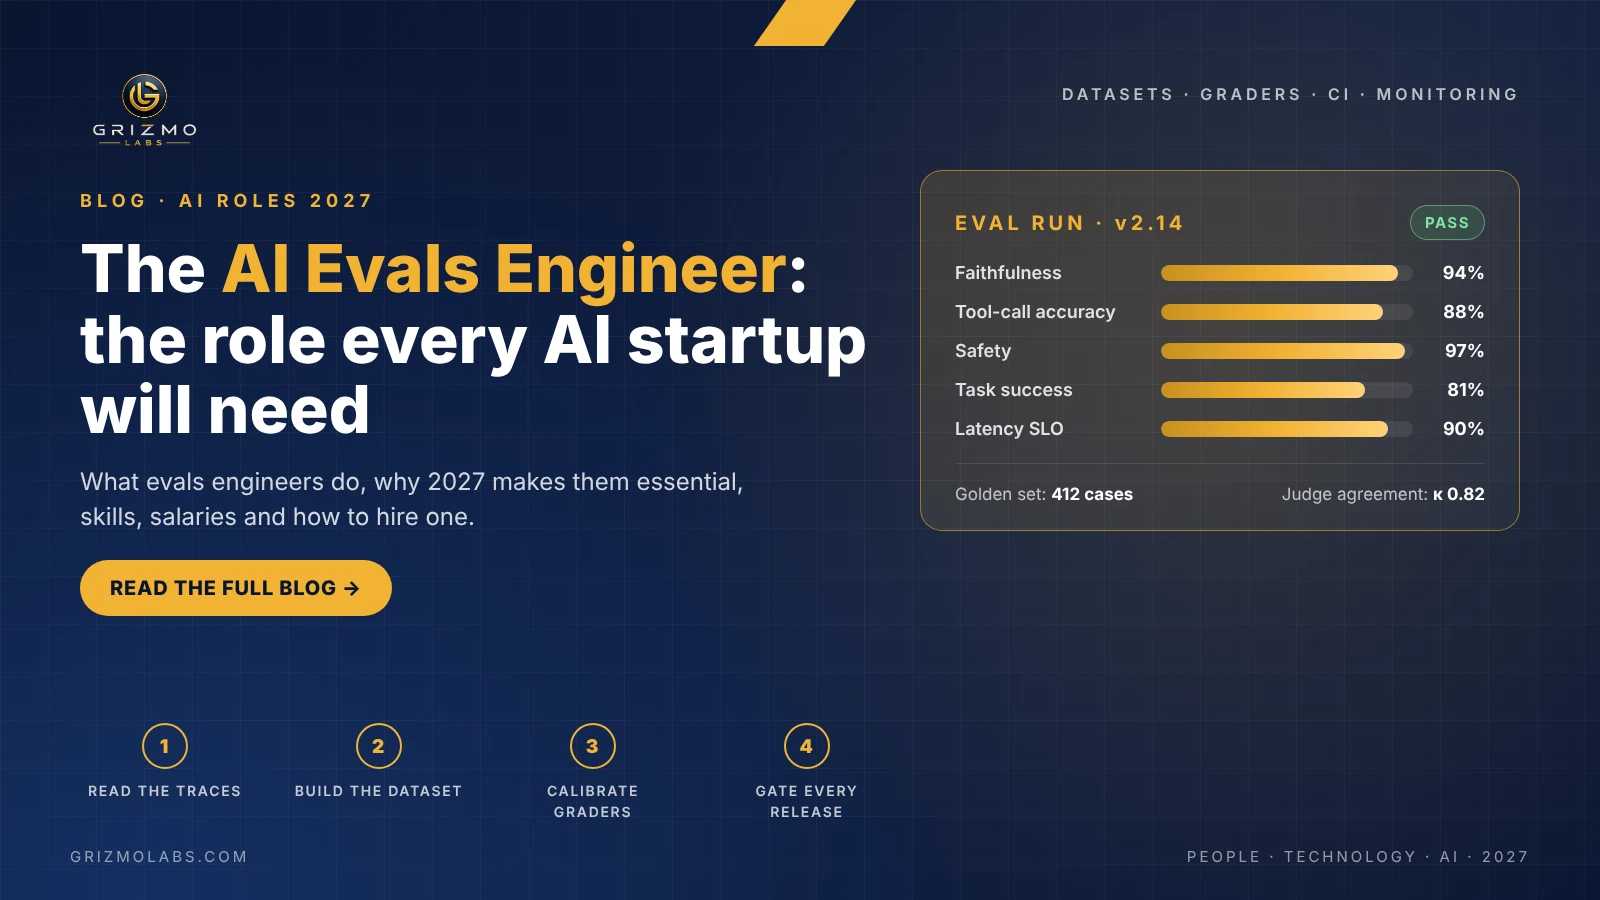
An AI evals engineer is the engineer who measures whether an AI product actually works. They build test datasets from real failures, design automated and human grading, gate every model or prompt change in CI, and monitor quality in production. In 2027, most AI startups shipping agents or LLM features to customers will need this role, usually as one of their first five AI hires.
Why now? In LangChain’s 2026 State of Agent Engineering survey of more than 1,300 professionals, 32% named output quality as the number one barrier to putting agents into production, ahead of latency and cost. Gartner predicts that over 40% of agentic AI projects will be cancelled by the end of 2027. The models are capable. What most teams lack is a reliable way to prove their product is getting better rather than worse with every release.
This guide explains what an AI evals engineer does, why 2027 is the year the role becomes essential, the skills and tools to look for, salary benchmarks in India and the US, and how to hire your first one.
Key Takeaways
- An AI evals engineer owns the quality of an AI product: test datasets, graders, release gates and production monitoring.
- Quality is the top barrier to production for 32% of agent teams (LangChain, 2026), and only 37% run online evals on live traffic.
- Good evals work in three levels: code-based assertions, LLM-as-judge plus human review, and A/B tests on user outcomes.
- The most important skills are error analysis, dataset design, statistics, judge calibration and production engineering.
- India AI engineering pay bands run ₹15–30 LPA mid-level and ₹30–70 LPA senior (Second Talent, Sep 2026), with eval specialists in the upper half.
- Hire your first evals engineer once you have real users, more than one model or prompt in production, and releases that regularly break quality.
In This Article
- What Is an AI Evals Engineer?
- Why Every AI Startup Will Need One
- What an Evals Engineer Does
- The Three Levels of AI Evals
- Evals Engineer vs Other Roles
- Skills and Tools
- When to Hire Your First One
- Salary in India and the US
- How to Interview
- Where to Find Evals Engineers
- The First 90 Days
- Frequently Asked Questions
What Is an AI Evals Engineer?
An AI evals (evaluation) engineer designs and runs the systems that measure how well an AI model, LLM feature or agent performs on the tasks that matter to users. They turn vague goals like “the answers should be good” into specific, repeatable tests, then run those tests on every change and on live traffic.
Anthropic’s careers page describes the goal of its model evaluations work as turning “ambiguous notions of intelligence into clear, defensible metrics.” At a startup, the job is more practical: make sure the support agent does not invent refund policies, the coding assistant passes the customer’s tests, and the new model you switched to is actually better.
Think of evals as the test suite for non-deterministic software. Traditional unit tests check that code returns the right answer. Evals check that a system producing a different answer every time is still right often enough, safe enough and useful enough to ship.
Why Every AI Startup Will Need an Evals Engineer in 2027
Three shifts are making evaluation the bottleneck for AI products: more agents in production, more models in the stack, and more customers and regulators asking for proof.

- Agents are in production: 57% of organisations now run AI agents in production, up from 51% a year earlier (LangChain, 2026).
- Quality is the blocker: 32% of those teams name quality as their primary barrier to production, ahead of latency at 20% (LangChain, 2026).
- Testing lags behind: Only 52% run offline evaluations on test sets, and just 37% run online evaluations on live traffic (LangChain, 2026).
- Models keep changing: Over 70% of organisations use three or more LLMs, and new models reach meaningful adoption within a month of release (Datadog, April 2026). Every switch is a quality risk that only evals can measure.
- Projects are failing: Gartner predicts over 40% of agentic AI projects will be cancelled by the end of 2027 due to costs, unclear value or weak risk controls. An MIT NANDA study found 95% of enterprise GenAI pilots had little or no measurable P&L impact.
- Buyers want proof: Enterprise customers increasingly ask for accuracy, safety and bias evidence during procurement, and the EU AI Act’s obligations for high-risk systems continue to phase in. Evals produce that evidence.
If you cannot measure whether your AI got better this week, you are not iterating. You are guessing.
Grizmo Labs
We covered this shift in The AI-Native CTO in 2027: when AI makes code cheap, verification becomes the scarce skill. The evals engineer is where that verification lives for AI features.
What Does an AI Evals Engineer Do?
An evals engineer runs a loop that turns production failures into permanent tests.
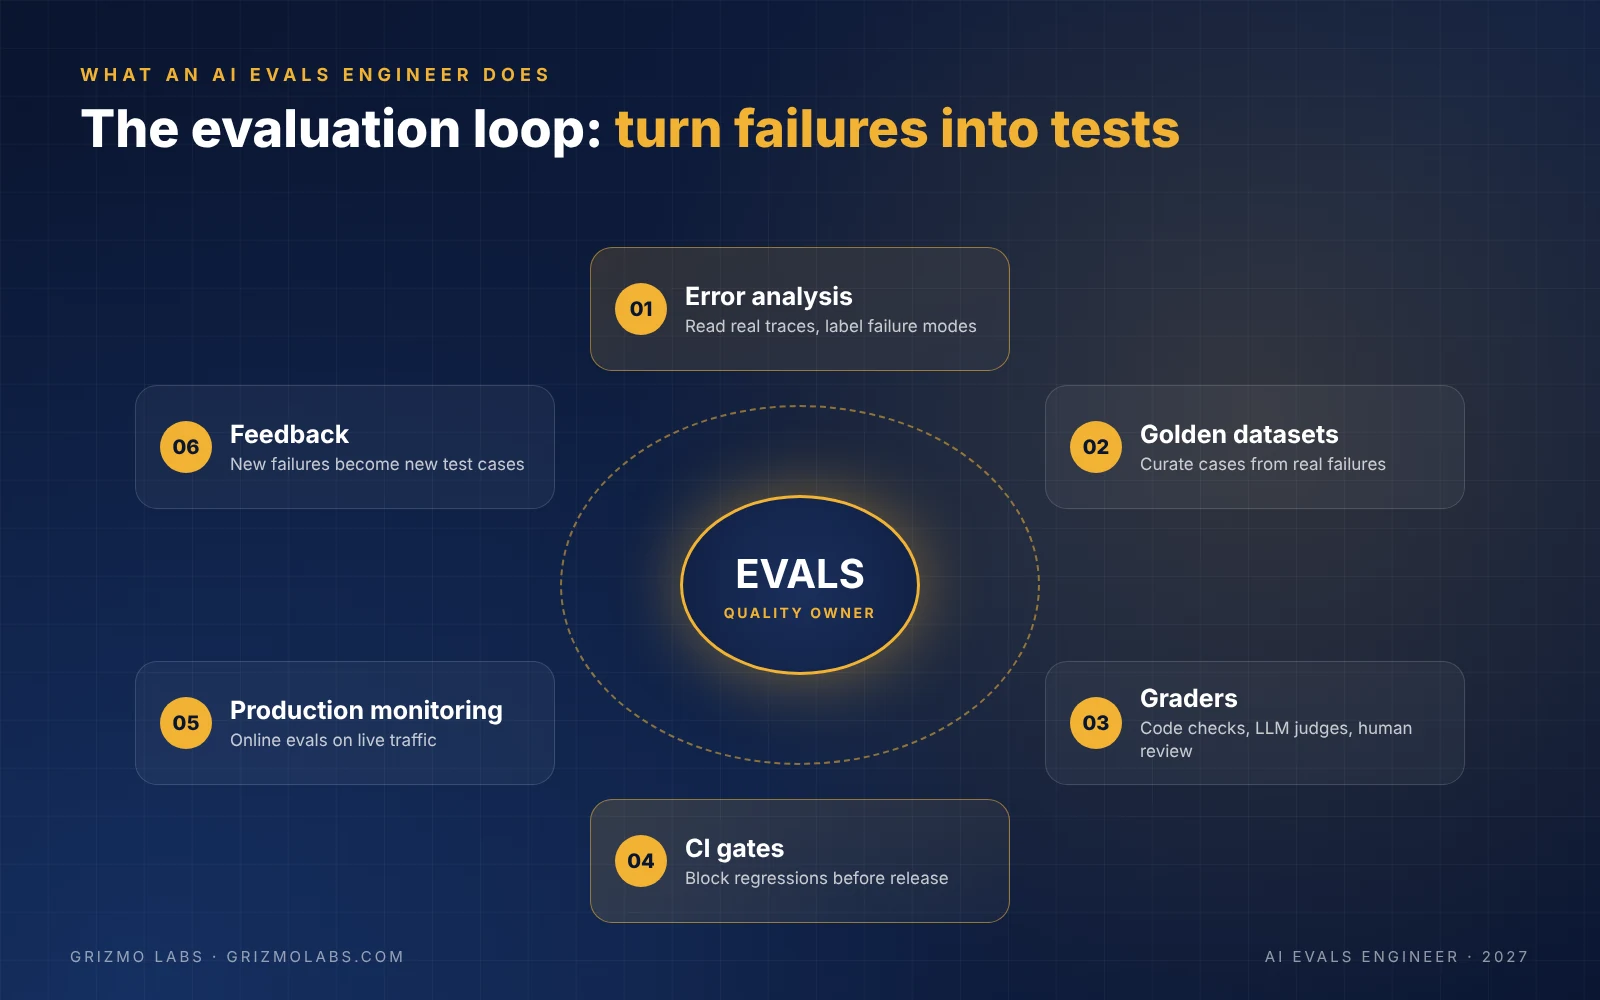
- Error analysis: Read real traces and conversations, and group failures into a taxonomy such as hallucinated facts, wrong tool calls, ignored instructions or unsafe output.
- Golden datasets: Turn those failures into curated test sets with expected behaviour, plus held-out splits so the team does not overfit.
- Graders: Write code-based checks, design LLM-as-judge rubrics, and calibrate those judges against human experts.
- CI gates: Run evals on every prompt, model, retrieval or agent change, and block releases that regress key metrics.
- Production monitoring: Run online evals on sampled live traffic and alert on quality drift.
- Feedback: Feed new failures back into the datasets, and report quality trends to product and leadership.
The Three Levels of AI Evals
Practitioners such as Hamel Husain describe evaluation in three levels. A strong evals engineer builds all three and knows which one each question needs.

Level 1: Code-based assertions
Fast, deterministic checks: valid JSON, correct schema, the right tool called with the right arguments, no banned phrases, no leaked personal data. These run on every commit and catch a surprising share of regressions.
Level 2: LLM-as-judge and human review
For qualities code cannot check, such as faithfulness to sources, helpfulness or tone, a model grades outputs against a rubric. Research by Zheng et al. found strong LLM judges agree with humans about 80% of the time, but they show position, length and self-preference biases. That is why judges must be calibrated against expert labels before you trust them.
Level 3: A/B tests on user outcomes
The final test is whether users succeed: tasks completed, tickets resolved, retention, revenue. These experiments are slower and costlier, so they validate the metrics in levels 1 and 2 rather than replace them.
AI Evals Engineer vs ML Engineer, AI Engineer and QA
| Role | Primary focus | Main output | Measured on |
|---|---|---|---|
| AI Evals Engineer | Measuring AI quality and safety | Datasets, graders, CI gates, dashboards | Regressions caught; trusted quality metrics |
| AI Engineer | Building LLM features and agents | Prompts, RAG pipelines, agent workflows | Features shipped |
| ML Engineer | Training and serving models | Models, training and inference pipelines | Model performance and cost |
| QA / Test Engineer | Deterministic software correctness | Test cases, automation suites | Bugs caught before release |
| Data Scientist | Analysis and experimentation | Insights, A/B test reads | Decision quality |
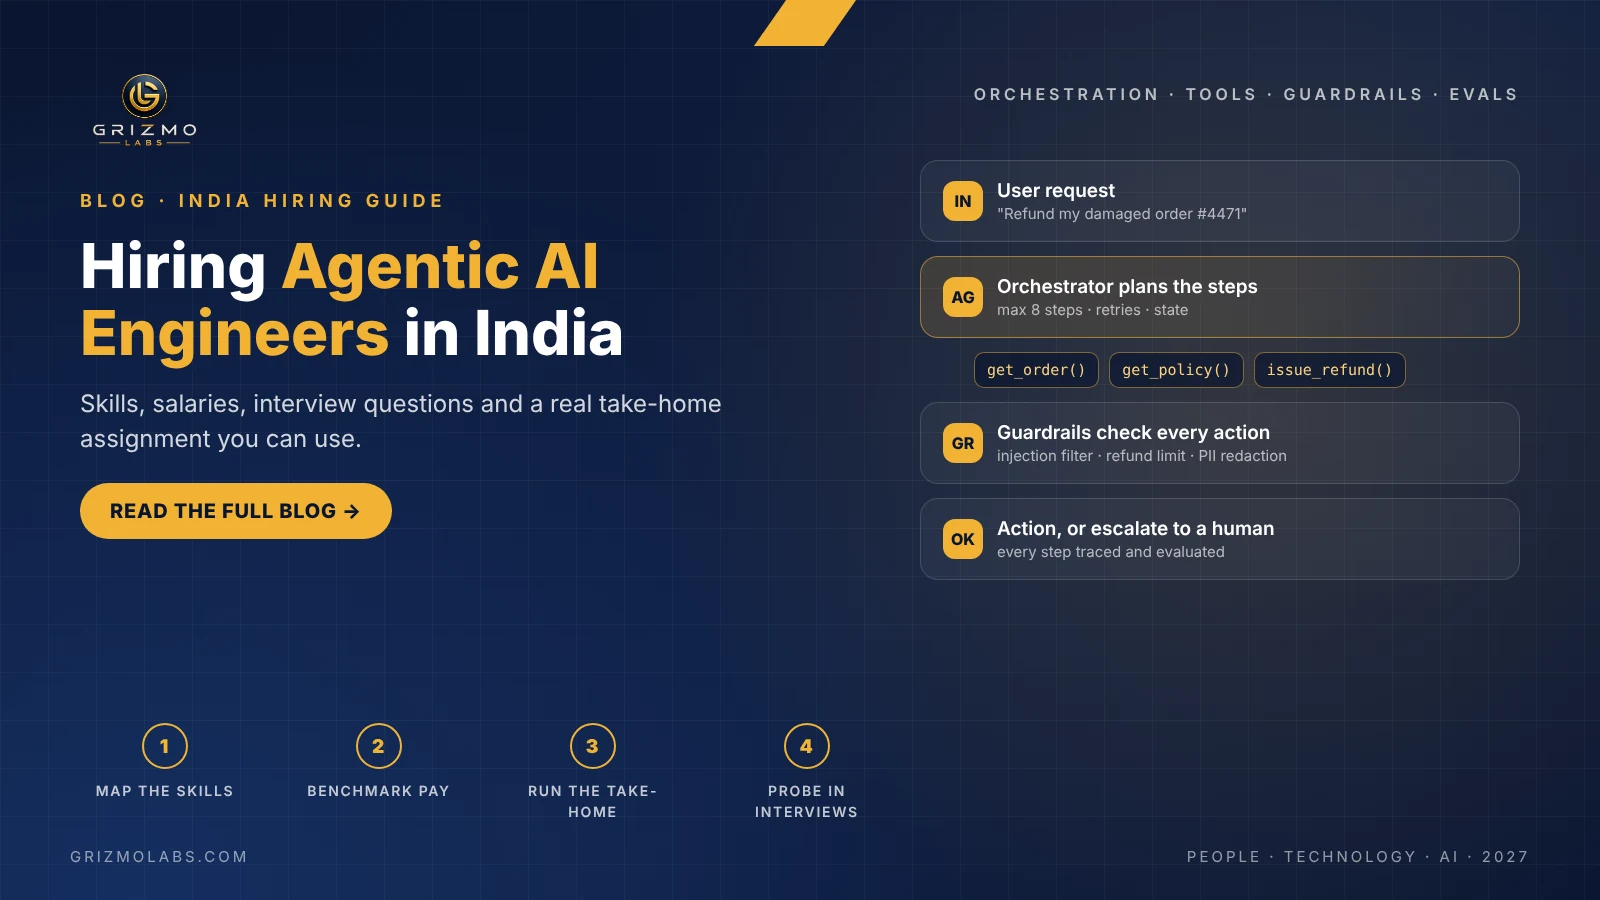
The evals engineer borrows from all four: the statistics of a data scientist, the test discipline of QA, and enough AI and ML engineering to understand why a system fails. See our breakdown of AI engineer vs ML engineer for how those two roles split. If you are building agents, our agentic AI engineer hiring guide includes a complete take-home assignment.
AI Evals Engineer Skills and Tools
1. Error analysis and failure taxonomies
The habit of reading hundreds of real outputs and grouping what went wrong. This is the most underrated skill in AI, and the clearest signal of a strong candidate.
2. Dataset design
Building golden sets that represent real users, cover edge cases and adversarial inputs, avoid contamination, and stay fresh as the product changes.
3. Statistics and experiment design
Confidence intervals, paired comparisons, statistical power and inter-rater agreement (such as Cohen’s kappa). An evals engineer should know when a 71% vs 69% result on 200 examples is noise.
4. LLM-as-judge design and calibration
Writing rubrics, preferring binary pass/fail over vague 1–10 scales, and measuring judge agreement with human experts before trusting automated scores.
5. Production engineering
Strong Python, data tooling (Pandas, Polars, DuckDB), async pipelines, CI/CD and tracing. Evals that do not run automatically do not get run.
6. Domain and safety judgment
Understanding what “good” means for the customer, whether that is legal accuracy, medical safety or financial compliance, plus red-teaming for prompt injection and harmful output. For a dedicated adversarial-testing hire, see our guide to AI security and red teaming engineers.
| Category | Common tools in 2026 |
|---|---|
| Eval frameworks | Promptfoo, DeepEval, Ragas, Inspect, OpenAI Evals, lm-evaluation-harness |
| Eval and observability platforms | LangSmith, Braintrust, Arize Phoenix, Langfuse, Galileo |
| Data and analysis | Python, Pandas, Polars, DuckDB, Jupyter |
| Pipelines and CI | GitHub Actions, OpenTelemetry tracing, cloud data warehouses |
Tools change quickly. Hire for the underlying skills; a strong candidate can learn a new platform in a week.
When Should a Startup Hire Its First Evals Engineer?
Hire a dedicated evals engineer when at least three of these are true:
- You have paying users or enterprise pilots relying on LLM outputs.
- You run more than one model, or switch models every quarter.
- Prompt or agent changes regularly break something nobody noticed until a customer complained.
- Customers or procurement teams ask for accuracy, safety or bias evidence.
- Your AI engineers spend more time arguing about whether a change is better than building the next one.
Before that point, assign eval ownership to a senior AI engineer and give them dedicated time. After it, every month without an owner adds quality debt that gets harder to unwind.
AI Evals Engineer Salary in India and the US
Evals is new enough that few salary surveys track it separately. The closest benchmark is AI engineering pay, with evals specialists who combine statistics and production experience sitting in the upper half of each band.

| Level | Experience | India (annual fixed) | US (total comp) |
|---|---|---|---|
| Junior | 0–2 years | ₹6–14 LPA | Varies widely |
| Mid-level | 3–6 years | ₹15–30 LPA | $230K–$340K |
| Senior | 6–10 years | ₹30–70 LPA | $340K–$480K |
| Lead / Staff | 10+ years | ₹60–110 LPA | $460K–$650K |
Sources: India bands from Second Talent’s AI engineer rate card (September 2026). US bands from the JobsByCulture AI evals career guide (June 2026), which reflects well-funded AI companies, not the whole market. Frontier labs pay more: HeroHunt reports Anthropic’s model evaluations research engineer roles at $500K–$850K in total compensation.
Budgeting Tip for 2027
For contract or remote work, Second Talent lists India AI engineer rates for international clients at $35–50 per hour for mid-level and $50–75 per hour for senior engineers. For a full-time evals specialist with shipped production evals, plan for the upper half of the India bands above. This is a Grizmo Labs estimate based on current search activity.
Our India vs USA hiring cost guide covers total employer cost, including benefits and statutory contributions.
How to Interview an AI Evals Engineer
Do not test evals engineers with algorithm puzzles. Test whether they can find failures, measure them honestly and build something that runs.
| Round | Format | What it tests | Strong signal |
|---|---|---|---|
| 1. Error analysis | 60 min: review 50 real (anonymised) outputs | Failure taxonomy, product judgment | Groups failures by root cause, not symptoms |
| 2. Statistics case | 45 min: “Model B scored 71% vs 69% on 200 items. Ship it?” | Confidence intervals, power, paired tests | Says “not yet” and explains why with numbers |
| 3. Judge design | 60 min: write and critique an LLM-as-judge rubric | Rubric design, bias control, calibration | Measures agreement with humans before trusting it |
| 4. Build exercise | Take-home (3–4 hrs) or live: eval harness for a RAG or agent task | Production code, CI thinking | Clean, reproducible pipeline with both code and LLM graders |
Green flags: they read traces before writing metrics, report confidence intervals, worry about benchmark contamination and are suspicious of a 98% pass rate.
Red flags: they quote public leaderboard scores as proof of quality, trust a single metric, or have never built an eval set from real user data.
Sample questions:
- “Our support agent’s CSAT dropped after a model upgrade, but offline evals improved. What happened, and what would you check first?”
- “How would you detect whether a model has seen your test set during training?”
- “How would you evaluate a multi-step agent that books travel, where many paths are valid?”
For structuring the wider loop, see our technical hiring pipeline guide.
Where to Find AI Evals Engineers in India
Few candidates have “evals engineer” on their profile. Look for the work instead:
- AI engineers at product startups who built eval pipelines for LLM features in production.
- Data scientists with experimentation backgrounds from e-commerce, fintech and consumer apps, where A/B testing rigour is standard.
- Search and ranking engineers, who have measured relevance and quality for years.
- ML engineers at Global Capability Centres (GCCs) working on model validation and responsible AI.
- QA and SDET engineers who have moved into AI testing, paired with strong statistics.
- Open-source contributors to eval frameworks such as Promptfoo, DeepEval, Ragas and lm-evaluation-harness.
Bengaluru, Hyderabad, Pune and Delhi NCR have the deepest pools, and strong remote candidates are available across India.
The First 90 Days of an AI Evals Engineer
- Days 1–30: Read production traces, build a failure taxonomy and ship the first golden dataset of 100–300 cases for the most important workflow.
- Days 31–60: Add code-based checks and a calibrated LLM judge, then wire evals into CI so every change gets a score.
- Days 61–90: Launch online evals on sampled live traffic, set quality alerts and start a weekly quality review with product and engineering.
AI Evals Engineer Hiring Checklist
- The top three AI workflows that need quality ownership are written down
- The level is decided: senior for a first hire, mid-level if a senior AI engineer can mentor
- The pay band is set in the upper half of AI engineering bands
- The JD names real failure modes your product has seen
- Sourcing covers AI startups, experimentation data scientists, search engineers and GCCs
- The loop covers error analysis, statistics, judge design and a build exercise
- Access to production traces and anonymised data is ready on day one
- A 90-day plan ends with evals in CI and online monitoring live
The Grizmo Labs Perspective
The startups we work with that ship AI fastest are not the ones with the most models. They are the ones that can answer, every week, “is our product better than it was last week?” That answer comes from evals, and someone has to own it.
Our advice for 2027: do not wait until a customer escalation forces the hire. Make evals an early AI hire, give them access to real traces from day one, and treat their quality dashboard as seriously as your revenue dashboard.
Conclusion: Evals Are How AI Startups Earn Trust
Models will keep getting better and cheaper, and every startup will have access to them. The advantage in 2027 belongs to teams that can prove their product works, catch regressions before customers do, and switch models with confidence. That is the job of the AI evals engineer.
If you are building agents or LLM features for real customers, the question is no longer whether you need this role. It is how soon you can hire one.
Frequently Asked Questions
What does an AI evals engineer do?
An AI evals engineer measures the quality and safety of AI systems. They build test datasets from real failures, write code-based and LLM-as-judge graders, run evaluations on every change in CI, and monitor quality on live production traffic.
Why will AI startups need evals engineers in 2027?
Quality is the top barrier to putting AI agents in production for 32% of teams (LangChain, 2026), most companies now use several models, and Gartner predicts over 40% of agentic AI projects will be cancelled by the end of 2027. Evals are how startups prove their AI works and keep it working.
What skills does an AI evals engineer need?
Error analysis, dataset design, statistics and experiment design, LLM-as-judge calibration, strong Python and data tooling, CI/CD, and enough domain knowledge to define what “good” means for users.
How much does an AI evals engineer earn in India?
Using AI engineering bands as the benchmark, mid-level engineers earn about ₹15–30 LPA and senior engineers ₹30–70 LPA in fixed pay (Second Talent, September 2026). Evals specialists with production experience typically sit in the upper half of these bands.
Is an AI evals engineer the same as a QA engineer?
No. QA engineers test deterministic software with fixed expected outputs. Evals engineers test non-deterministic AI systems, so they rely on statistics, curated datasets and calibrated graders rather than simple pass/fail assertions alone.
When should a startup hire its first evals engineer?
When you have real users relying on LLM outputs, use more than one model, and see releases regularly break quality without anyone noticing. Before that, a senior AI engineer can own evals part-time.
Sources and Methodology
Figures come from the sources below, accessed in November 2026. Survey results are self-reported. Salary data for evals roles is limited, so AI engineering bands are used as the India benchmark, and Grizmo Labs estimates are labelled as such.
- LangChain: State of Agent Engineering (1,340 respondents, surveyed Nov–Dec 2025)
- Datadog: State of AI Engineering (21 Apr 2026)
- Gartner: Over 40% of agentic AI projects will be canceled by end of 2027 (25 Jun 2025)
- The New Stack: coverage of the MIT NANDA enterprise AI study
- Zheng et al.: Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena (2023)
- Second Talent: AI Engineer salary and rate card, India (14 Sep 2026)
- JobsByCulture: AI Evals Engineer career guide 2026 (6 Jun 2026)
- HeroHunt: How to recruit AI evals engineers (26 Aug 2026)
Hire Your AI Evals Engineer with Grizmo Labs
Your evals engineer decides whether your team ships with confidence or ships and hopes. It is one of the hardest AI roles to assess in a standard interview loop.
Grizmo Labs runs specialist searches for AI and LLM engineers, evals engineers, forward deployed engineers and founding engineers across India, for startups and global companies.